
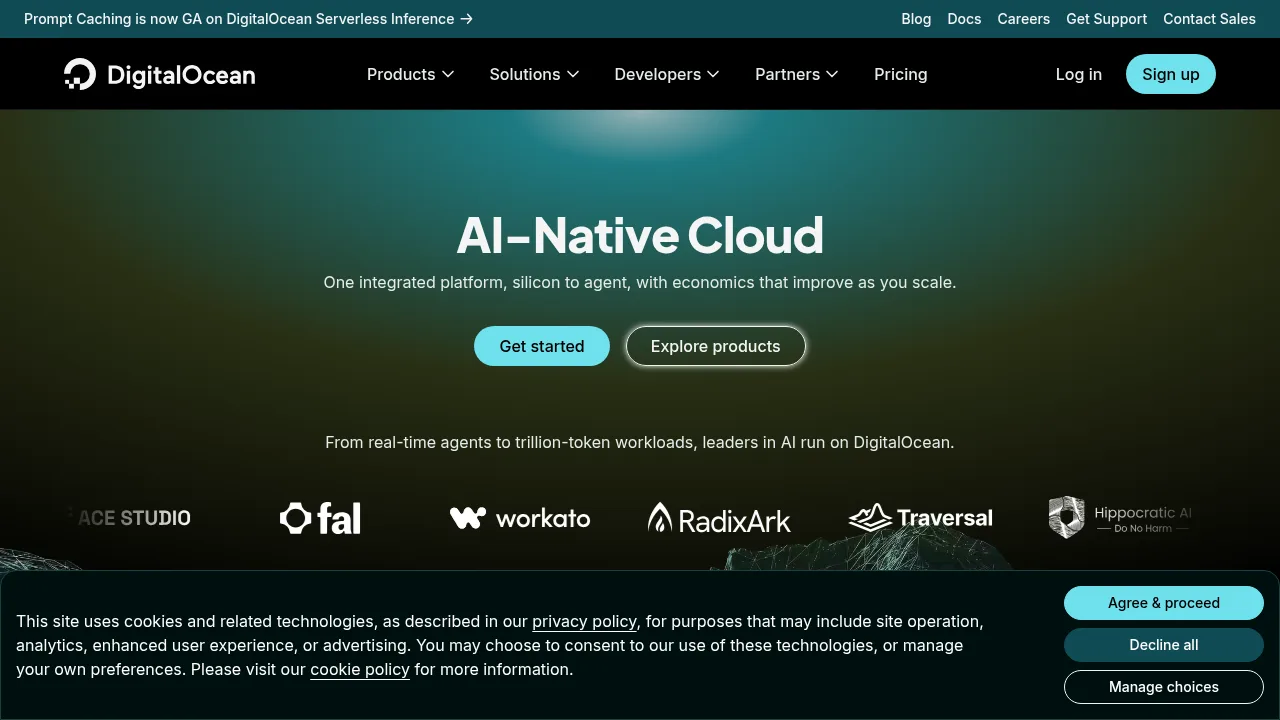
What is DigitalOcean?
DigitalOcean is a cloud platform that combines compute, managed databases, storage, and AI inference services under a single account. It serves developers and companies building applications or running AI agents across 20 data centers in 13 regions. All resources, including GPU servers and serverless inference, share one invoice with private networking between resources in the same region.
What are the features of DigitalOcean?
- Serverless model inferenceCalls over 85 open-source and frontier models through an OpenAI-compatible endpoint, billed per token with scale-to-zero pricing.
- Managed agent hostingRuns agent frameworks such as LangGraph, CrewAI, or Claude Code in isolated MicroVMs that pause when idle.
- Inference routing (Inference Router)Automatically selects a model per request based on defined cost or speed criteria without requiring code changes.
- GPU compute instancesProvides Droplets powered by NVIDIA H100, H200, B300, and AMD Instinct MI300X, MI325X, MI350X, and MI355X hardware.
- Custom model importImports Safetensors weights from Hugging Face for use with Dedicated Inference on supported architectures.
- Agent observability toolsRecords agent actions, flags performance shortfalls, and tests changes through Insights, Signals, and Evaluations services.
What are the use cases of DigitalOcean?
- Prototyping AI applicationsStart with Serverless Inference to call foundation models via API and pay per token before committing to dedicated infrastructure.
- Running always-on production agentsDeploy an existing harness like Codex CLI or Hermes in a Managed Agents MicroVM alongside governed access to over 16,000 tools.
- Hosting large open-weight modelsRun models such as DeepSeek V4 Pro using Dedicated Inference or GPU Droplets while keeping databases and object storage in the same account.
DigitalOcean Pricing Information:
- Serverless InferencePay-per-token billing with scale-to-zero pricing; supports 85+ models.
- Managed AgentsCompute charges pause when the agent's MicroVM is idle.
- Dedicated Inference and GPU DropletsPricing depends on workload; see current pricing for details.